Capture ChatGPT and Gemini search fan-outs and sources
Capture, analyze and export every ChatGPT Search and Gemini conversation: query fan-outs, consulted and cited pages, products, ads, entities, and how each engine searches behind its answer.
Powered by RESONEOVersion 6.0.1 · October 2026
Gemini joins ChatGPT: fan-outs, consulted pages, cited passages and question classifier
The extension is now called Search & fan-out capture, and it captures Gemini too. For each question asked on gemini.google.com, it records the fan-out queries, the pages consulted, the pages cited with the passage used, and how Google classified the question. On ChatGPT, it detects ads. The interface moves to RESONEO's design, with one menu per engine.
Gemini fan-outs
Gemini does not send its search queries along with the answer. The extension re-reads the conversation half a second after the answer ends and retrieves every fan-out query, image searches included. You need to be signed in to a Google account: without one, Gemini does not keep the conversation and the fan-out stays out of reach.
Consulted pages, cited pages, passages
For each search, the pages Gemini consulted. For each cited page, the passage Gemini highlights when you open the source, and the sentences of the answer that rely on it. Pages cited through a plain link in the text count too. A funnel sums up the path: searches, pages consulted, pages cited, share of the answer tied to a source.
The question classifier
Google scores every question across 35 topics, 47 tasks, 22 follow-up types and a sentiment. The scores arrive at the very start of the answer, whatever the model, even when signed out. They describe the question: asked to two different models, it gets nearly the same scores.
Model, location and withdrawn answers
Each turn's card shows the model used, the language of the question and of the answer, the country and the location Gemini relied on, with where it came from (for example the home address saved in your places). When Gemini shows an answer and then replaces it with a refusal, the extension keeps the withdrawn text.
Gemini dashboard, brands and projects
A Dashboard brings all Gemini conversations together: fan-out queries, word cloud, domains and URLs consulted or cited, classifier topics and tasks, places, videos, products. Brand tracking covers the answer and the cited pages. Projects created for ChatGPT apply to Gemini as well, and everything exports to CSV or JSON.
ChatGPT ads
ChatGPT inserts sponsored units under some answers. The extension detects them and lists, for each one, the advertiser, its ad account ID (the same from one conversation to the next), the format (product card or image card), price, rating, landing page and campaign. The Dashboard ranks advertisers and shows the share of conversations carrying an ad. In our captures, ads only show up on free accounts.
New design
The interface follows RESONEO's design: navy blue, Montserrat, green for ChatGPT, teal for Gemini. Tabs sit in two menus, ChatGPT and Gemini, each with its own Analyze and Dashboard. Texts were rewritten and tooltips explain the columns. Fonts are bundled: the extension calls no outside service to render.
Also since 5.1.2
- Loader: pick the thinking effort before each prompt (instant, light, medium, high, Pro), compatible with ChatGPT's new effort slider. The model actually served is shown for each conversation.
- Pro mode: long Pro-mode turns are captured in full, fan-out included. The extension recorded them, then dropped them from its own list; this is fixed.
- Duplicate ads: when ChatGPT sends the same ad twice, a single row is shown.
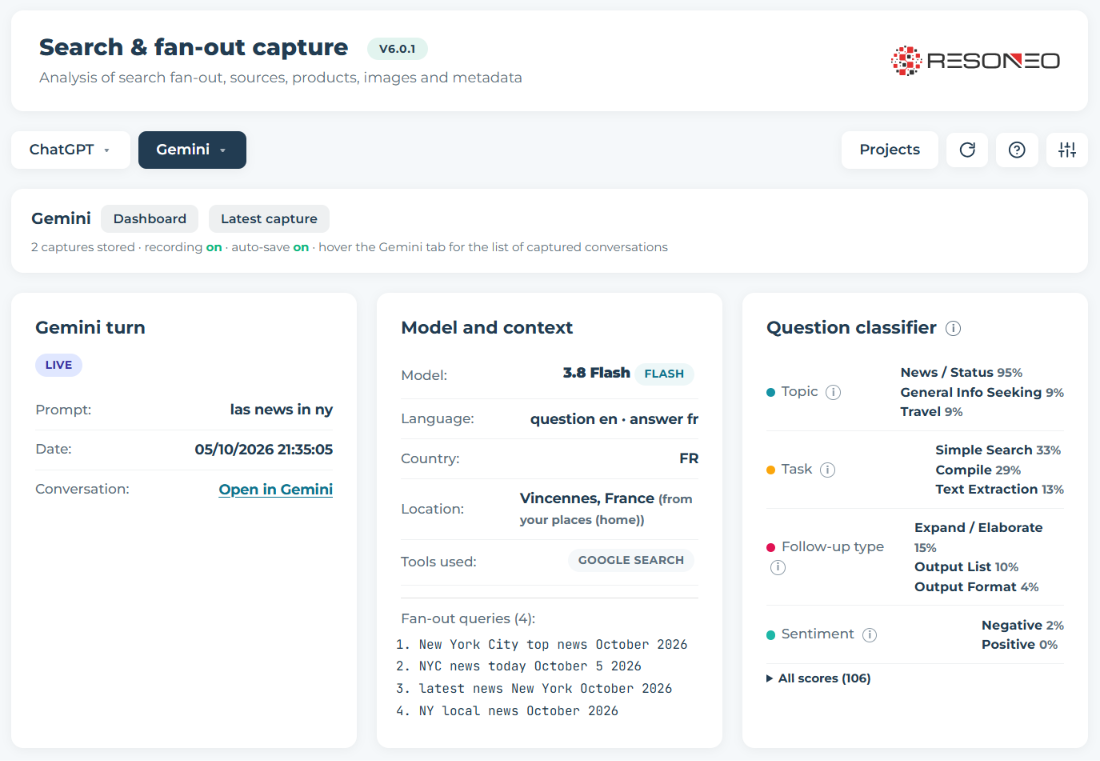
The Gemini tab in the new design: for each turn, the model, the location, the fan-out queries and the question classifier.
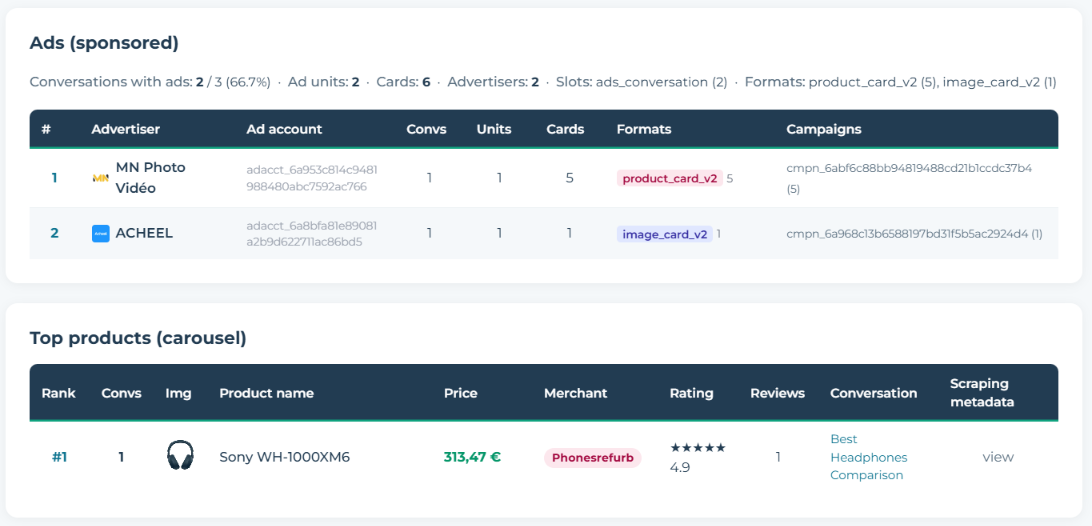
ChatGPT ads in the Dashboard: advertisers, ad accounts, formats and campaigns, next to the carousel products.
Version 5.1.2 · July 2026
From the retrieval net to the citation: measuring a URL's journey, not just listing it
Until now the plugin listed what ChatGPT displayed. It now measures what happens in between: how many URLs the turn retrieved, how many were promoted to the top section, how many end up as a citation pill. This release also folds in what we learned from our study across 683 conversations — notably that the result_source field vanished from the stream between 20 and 22 July, forcing the pipeline to be inferred rather than read.
Rebuilt pipeline classifier
Since result_source vanished from the stream, the engine behind each result has to be inferred. We compared 21,664 still-labelled results: both engines leave serialization artefacts in the snippet. OpenAI's own index returns page text — double spaces (51 % of its snippets, never on the Google side), non-breaking spaces, image alt text, markdown. Google returns a truncated SERP snippet — ending in "Read more" (49 %), relative-date prefix (32 %). The plugin now applies these markers as a cascade ahead of any length heuristic: two thirds of results are attributed by a rule at 99.9 % purity, and labrador recall rises from 88.8 % to 97.9 % at unchanged precision.
Listed → promoted → cited funnel
Three levels measured per conversation: every URL in the side panel, those promoted to the top section — separating the lead source from secondary ones — and those that become the lead source of a citation pill. An aggregate pyramid applies the same reading across all filtered conversations, with a result-nature selector and the promotion rate within each nature. Carousels are counted separately.
Why a URL has no snippet
A URL with no snippet is no longer an empty cell: the plugin gives the reason. Opened page, no index snippet for pages the model read itself, this pipeline serves no snippet for the scientific and video channels, rarely for forums, served empty for the rest. The Total lines: read header is no longer miscounted as a snippet.
Result nature and labrador badge
Eleven named, colour-coded natures replace the raw ref_type: web search, news, scientific, forum, video, local, product, image, weather, opened page, no type. And since result_source is gone from the stream, a 🐕 badge flags results attributed to labrador, OpenAI's own index, with the format signals behind that call shown on hover.
Pages opened by the model
A dedicated block for the pages the model actually opened and read, detected from the read marker and view references, deduplicated by URL. Not to be confused with links merely displayed: these are the only pages whose full content reached the model.
Unambiguously named surfaces
Every link now carries its display surface: citations (sidebar top), More panel, footnote strip, widgets, opened page, residual. Supporting websites, which account for over a third of citations, are counted as such rather than dropped.
Reconstruction reliability
ChatGPT's content blocks are not sent in one piece: their type is set by successive patch operations in the stream. The plugin now replays those operations path by path, which surfaces widgets that previously escaped detection. Surfaces are cross-referenced by normalized URL, never by reference coordinate — numbering spaces differ between surfaces and would pair unrelated URLs.
Version 3.4 · June 2026
Three new sourcing signals captured from ChatGPT's search conversations
Following the research by Suganthan Mohanadasan, we extended the plugin to capture three new signals from ChatGPT's search conversations. We also fixed a few bugs along the way.
Turn use case
We now surface the server-side turn_use_case field, which reveals the intent category ChatGPT assigns to each turn (e.g. shopping). It tells you how the model framed the request before answering, a useful signal for spotting when a query triggers commercial vs. informational behavior.
Reference types
A breakdown of the inline citation markers embedded in the response (e.g. product (9), search (3), news (1)). Parsed directly from the answer's reference tokens, it shows the mix of source types ChatGPT actually cited (products, web search results, news, images, and so on) and in what proportion.
Sourcing pipelines
Each cited web result carries a result_source field identifying the data provider that fetched it: Bright Data, Oxylabs, Licensed (Labrador), or SERP. We aggregate these per conversation (e.g. oxylabs (10), bright (6)) and chart them in the Dashboard, so you can see which sourcing infrastructure is behind the citations your content competes against.
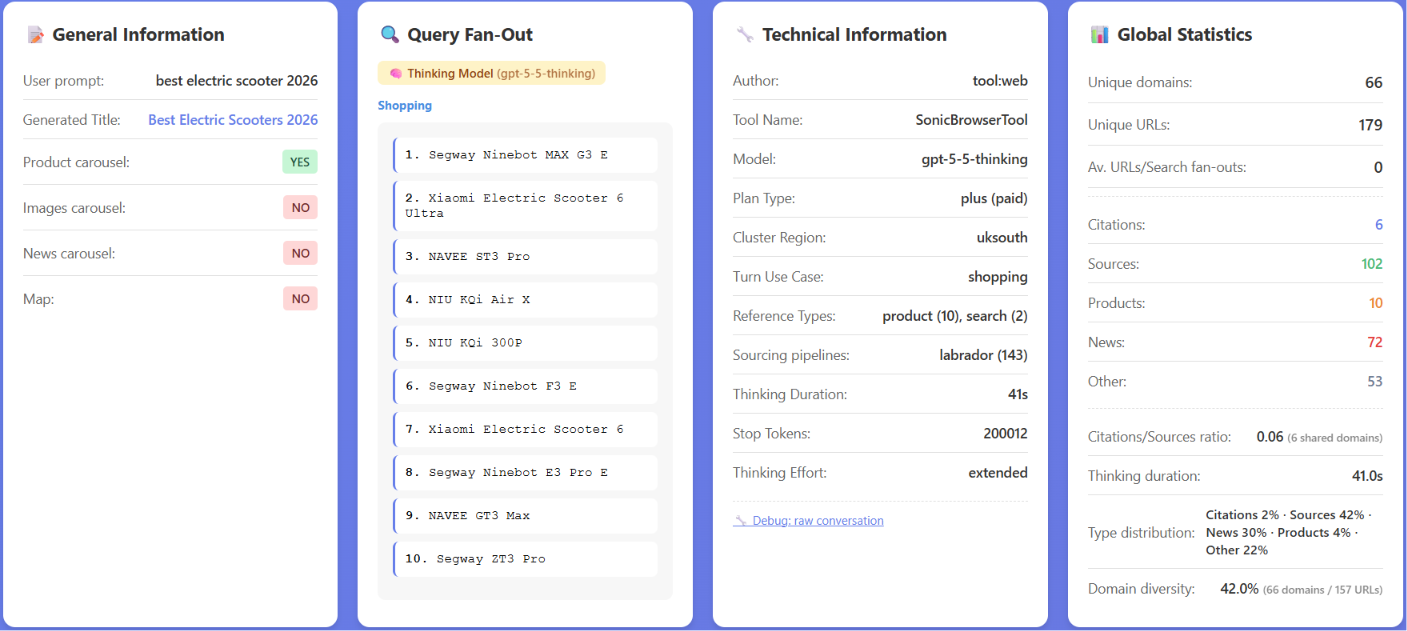
Turn use case, reference types, and the sourcing pipelines (Bright Data, Oxylabs, Licensed, SERP) behind every cited result.
Version 3.3 · March 2026
GPT-5.3 / GPT-5.4 support, Thinking & Extended Thinking capture, Map Carousel
This release brings full support for the GPT-5.3 model, which no longer shows fan-out search queries but still leverages image and shopping fan-outs, and GPT-5.4 thinking & extended thinking. The analyzer now correctly handles this new behavior and adjusts statistics accordingly.
- Map Carousel block - a new block recovers and displays map/local results returned by ChatGPT's browsing engine.
- Chain-of-Thought & Thinking Summaries - significantly improved detection, with better extraction of reasoning steps, summaries, and thought content.
- Entity identification - refined: generic placeholders are now filtered out, and entity types (products, places, organizations...) are more accurately classified.
- Technical Information panel - now reports all turn reference types (search, cite, product, forecast...) with counts.
- Top URLs table - includes a new Ref column showing each link's role in the search result groups.
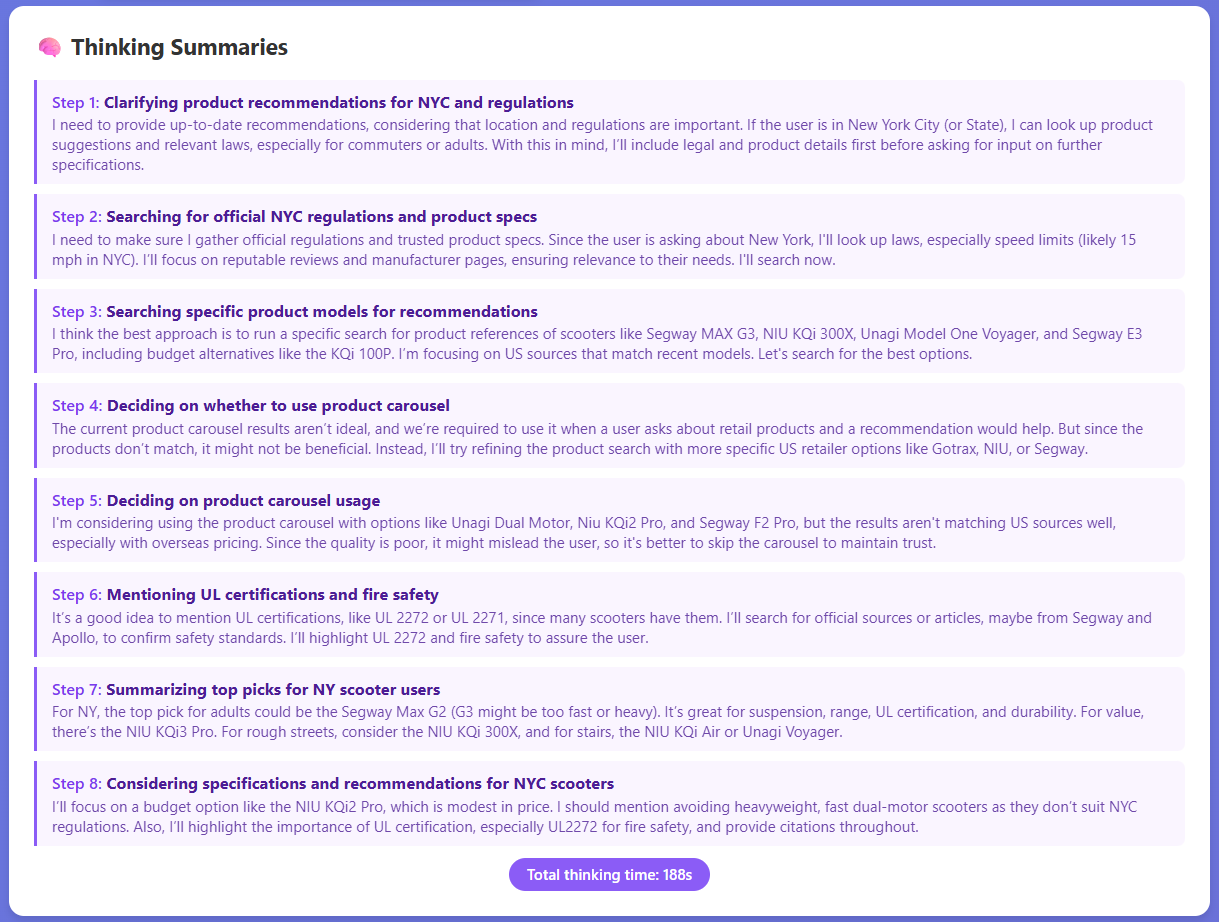
Capture of Thinking & Extended Thinking: reasoning steps and summaries are recovered (up to 8 steps in Extended Thinking).
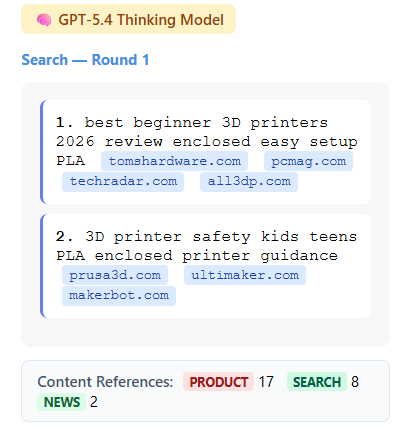
Domain filtering surfaced from the model's reasoning, illustrating the source selection visible in Thinking Summaries.
Version 3 Changelog · December 2025
Automatic loader, mentions monitoring & Map carousel detection
- Prompt Loader - automate bulk prompt submissions to ChatGPT and capture all responses automatically for batch analysis.
- Brand & Competitor Mentions Tracking - monitor your brand and competitors. Configurable aliases, mention counts, and contextual passages.
- Top Brand Mentions table - aggregated brand visibility with clickable conversation links.
- Map Carousel Detection - capture location-based results with names, addresses, ratings, and coordinates.
- Title and Snippet detection for source links.
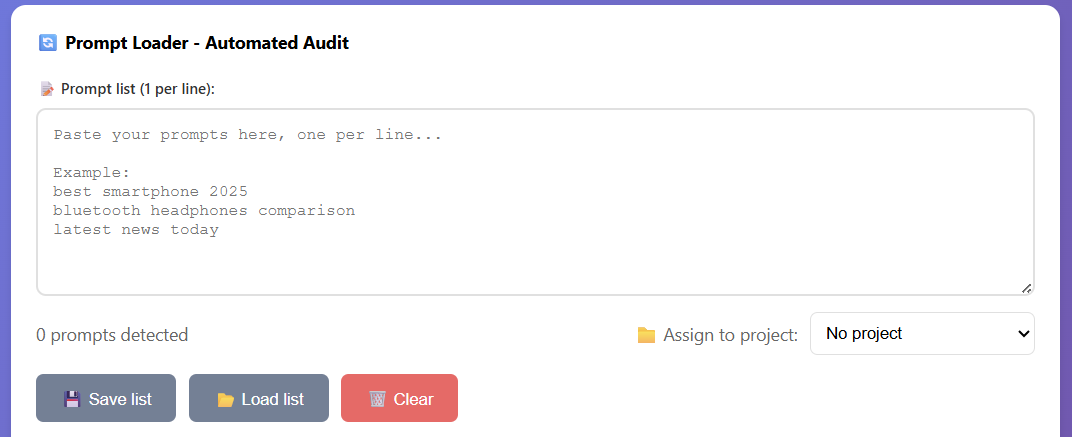
Queue multiple prompts, auto-submit them to ChatGPT one by one, and automatically capture all responses.
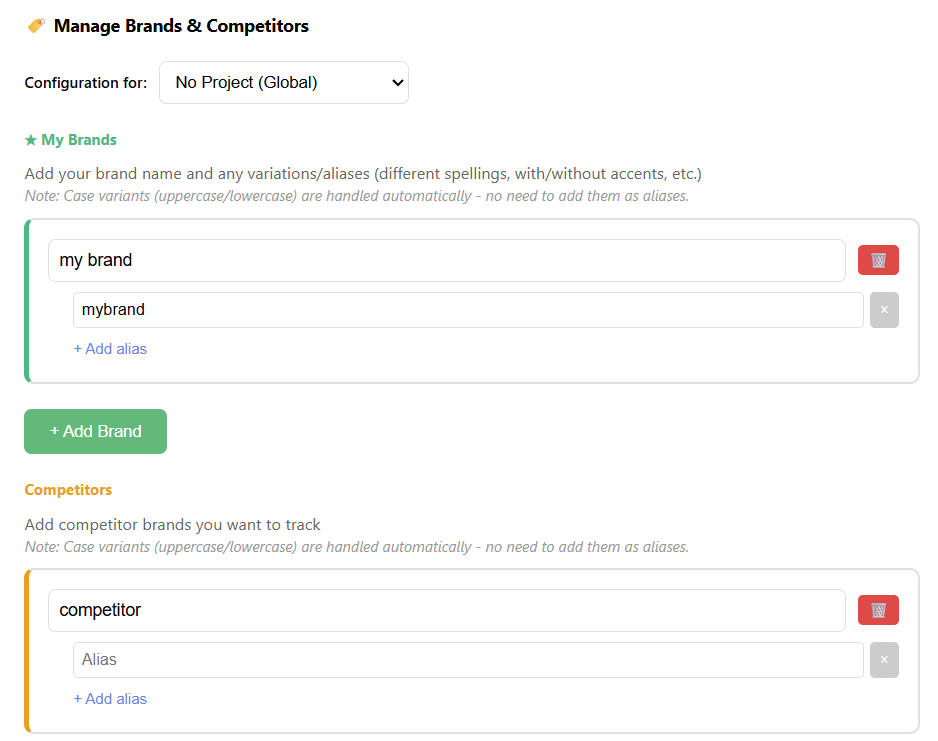
Monitor your brands & competitors (and their alias).
Version 2 · October 2025
Major updates and new features
Advanced fan-out detection
Differentiation between Search (traditional), Shopping (shorter queries using SearchApi.io to scrape Google Shopping), and Images fan-outs (more numerous, likely using Bing or a proprietary index).
Entity recognition (NER)
Detection of entities flagged by ChatGPT (news-related) and product_entity extraction from shopping carousels, likely corresponding to products anchored in the Google Shopping Graph.
Project management system
Group conversations by themes (brand/non-brand, client, topic...). Filter the global dashboard by project for targeted analysis.
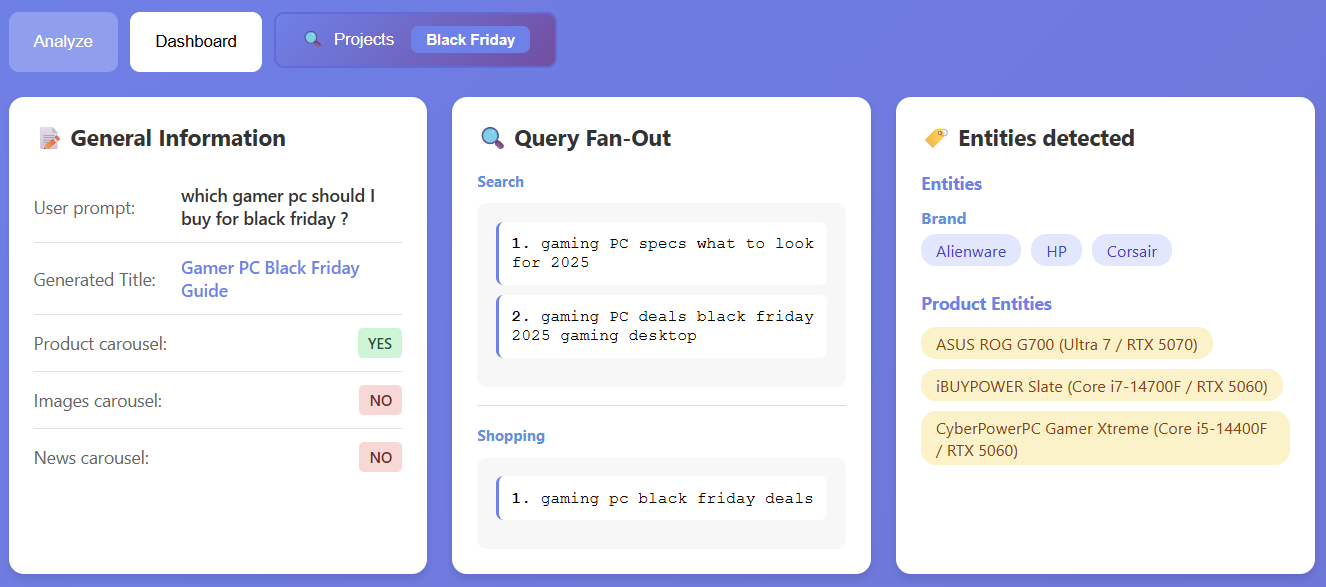
Entity recognition, product entities detection, fan-out types differentiation + projects filter.
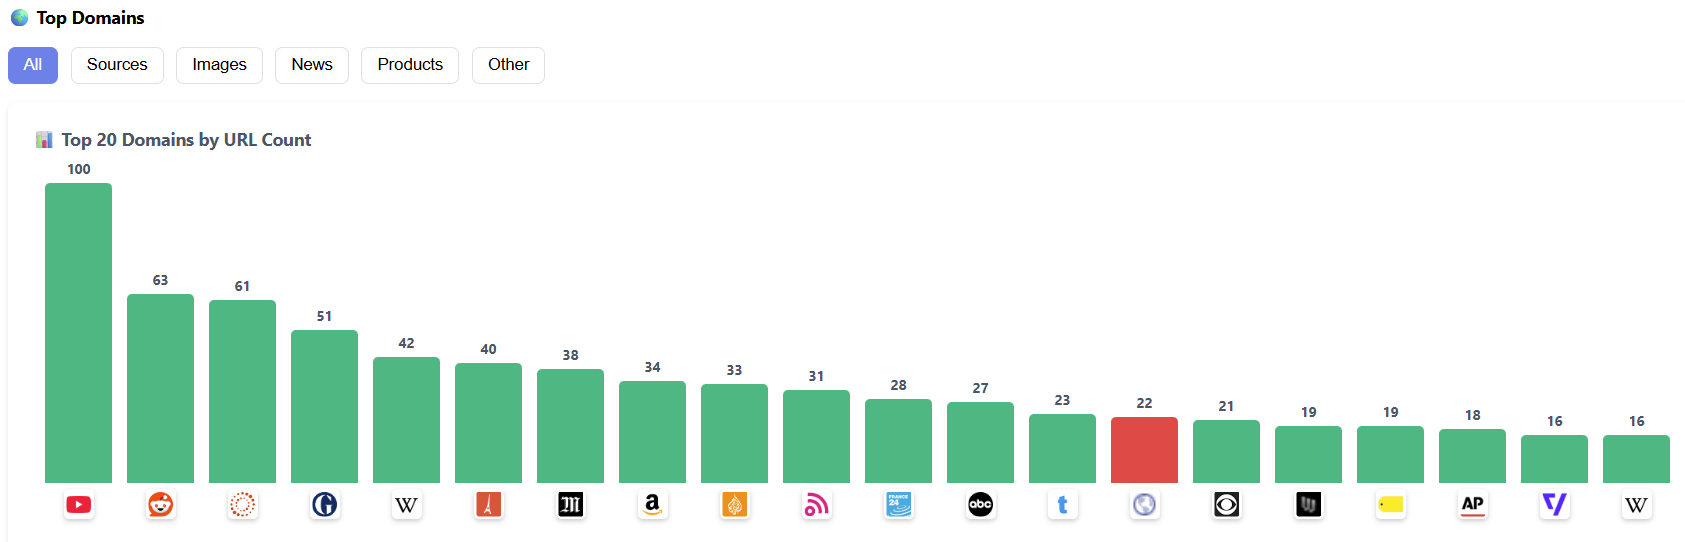
Top domains analysis with visual graph.
Dashboard screenshots
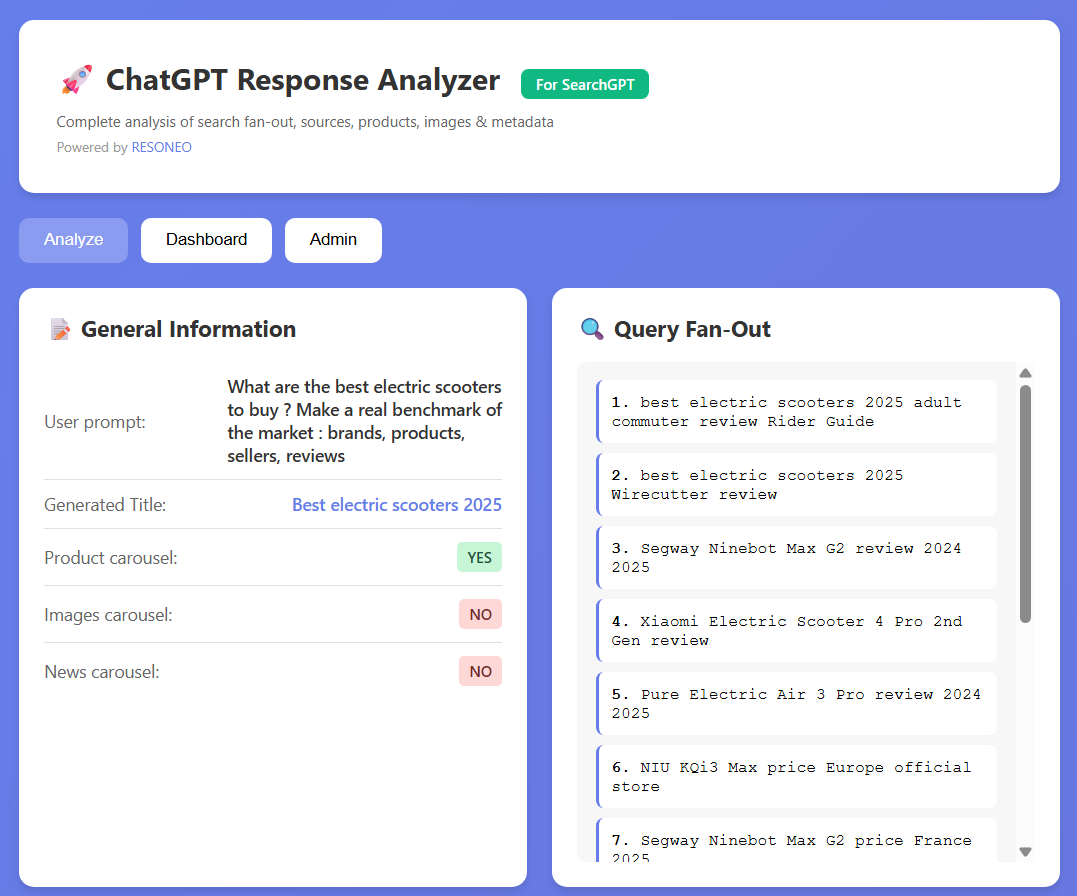
Query fan-outs & general analysis
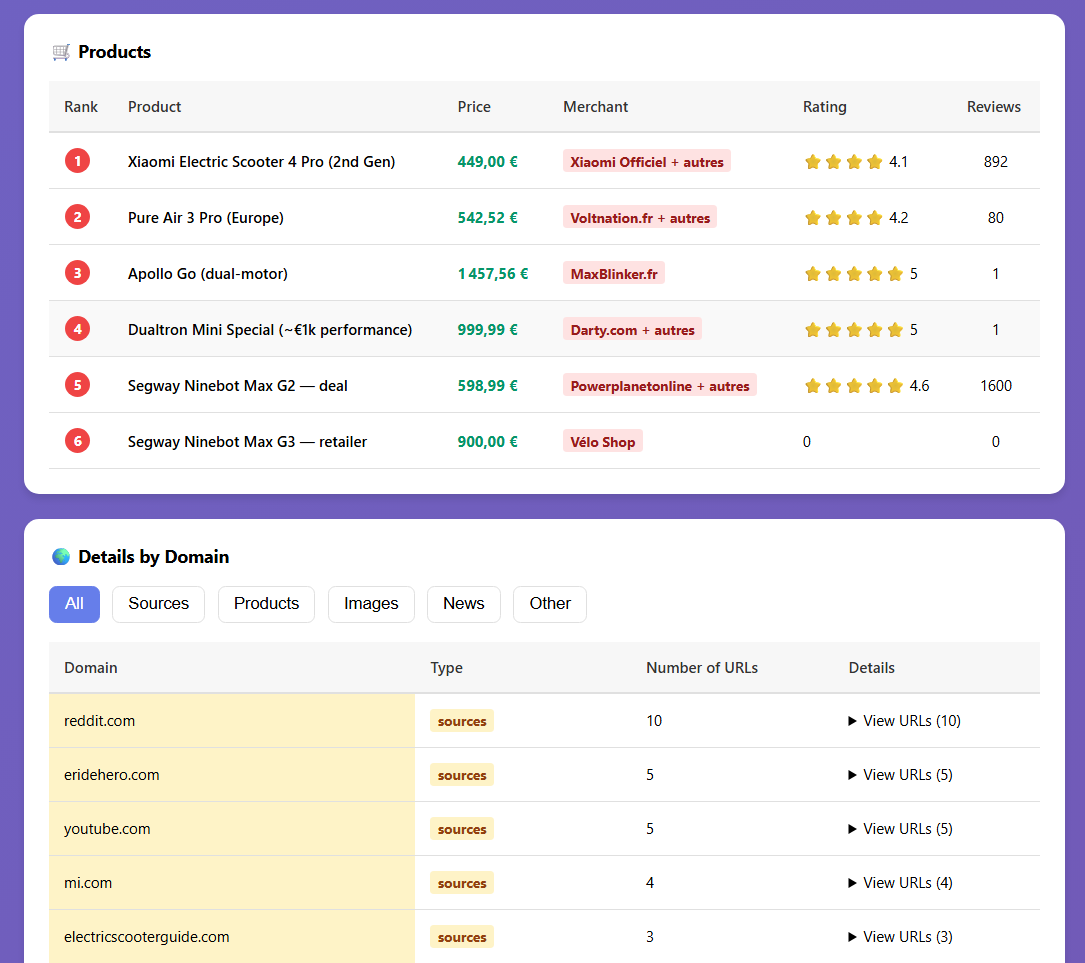
Product details with prices & reviews
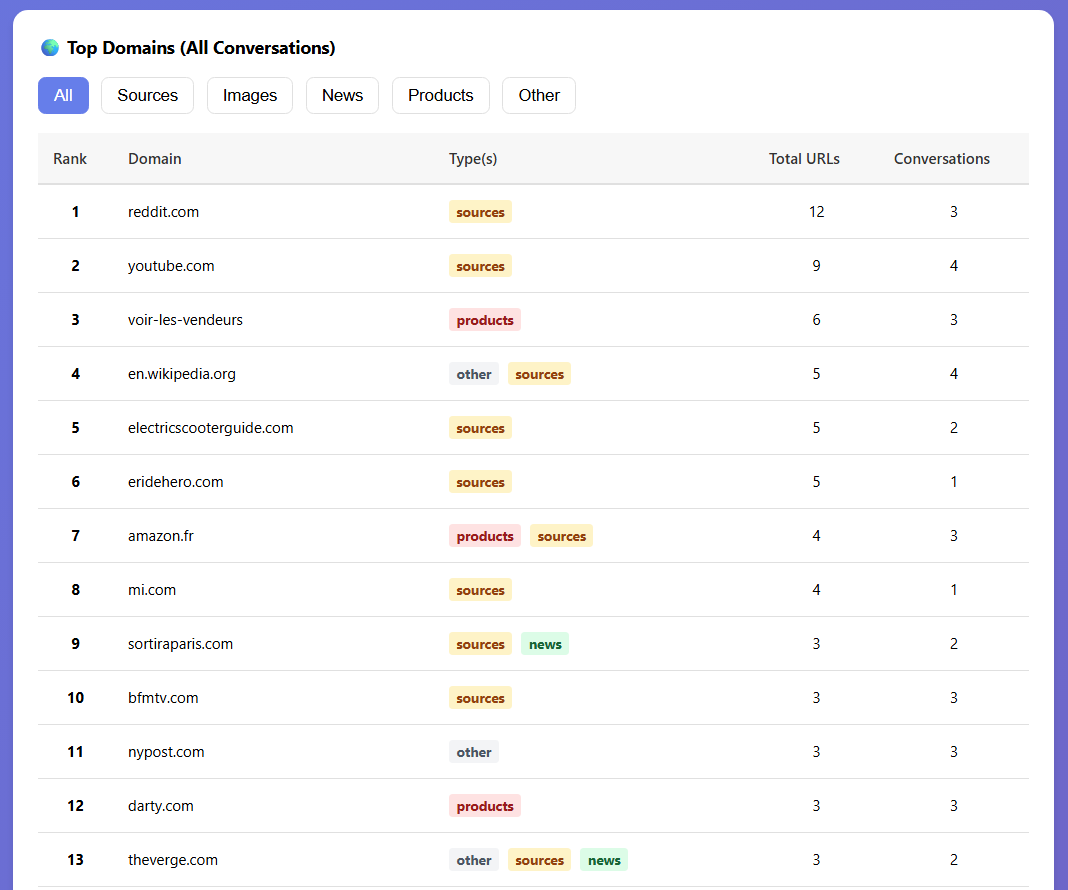
Top domains & source citations
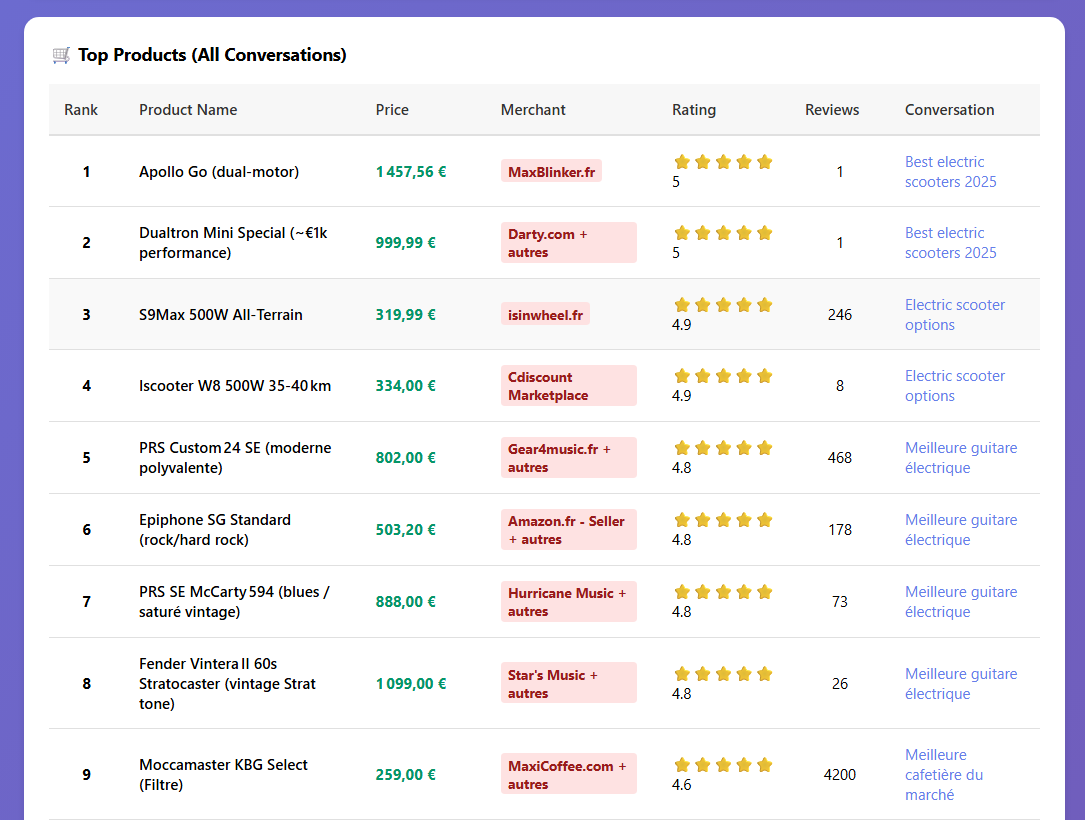
Cross-conversation product analytics